An AI agent that reads a CRM, calls an internal API, and sends email on someone’s behalf needs three questions settled before it reaches production: who it is, which path its requests take, and how anyone will reconstruct what it did afterward. Teams that run their APIs behind a gateway such as Google Apigee API Management have applied a version of this rule to applications for years: no client calls a backend directly, and access policy sits in one layer outside the individual services.
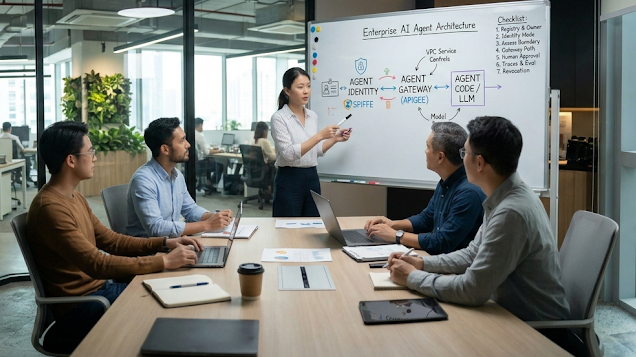
Google has now built the same rule into its agent stack. At Google Cloud Next ’26, the company introduced Agent Identity, a dedicated principal type for agents, together with Agent Gateway, which enforces policy on every agent-to-agent and agent-to-tool connection. The design of these components maps the places where enterprise agent setups tend to break: identity, routing, and observability. All three belong in the architecture before the first line of agent code.
Why do enterprise agent projects stall before production?
Gartner expects more than 40% of agentic AI projects to be canceled by the end of 2027, and it names escalating costs, unclear business value, and inadequate risk controls as the reasons. Of the three, risk controls are the one an architecture decision can address on day one.
Survey data shows how wide that control gap already is. In the JumpCloud Agentic IAM Pulse Report, 72% of organizations have AI agents in use, while 92% report serious limits on scaling them safely. Of the same organizations, 66% give agents the same or broader system access than human employees, and 55% have no centralized kill switch that cuts an agent’s access across all systems.
Each of these figures describes an operational question without an owner: which identity an agent runs under, which endpoints it can reach, and who can switch it off when something goes wrong. A better model answers none of them.
What changes when an agent gets its own identity?
When agents run under shared service accounts or a developer’s personal token, an audit log can show which account acted, but it cannot show which agent did it or who is responsible for that agent. In Google’s announcement of the generally available agent features, a Best Buy cloud platform engineering manager describes the result: orphaned service accounts, unclear ownership, and permissions that grew over time.
Agent Identity treats an agent as its own principal, separate from both human users and generic service accounts. The identities are built on the open SPIFFE standard, provisioned automatically, and able to distinguish an agent acting autonomously from one acting on behalf of a user. For the second case, Agent Identity Auth Manager, now in preview, handles the OAuth flows, credentials, and tokens on the agent’s behalf.
Once each agent is a separate principal, familiar access controls apply to it. IAM Allow and Deny policies for agent identities are generally available. Principal Access Boundary sets hard limits on resources an agent can never reach, whatever permissions it inherits, and the upcoming Unified Access Policy can require human approval before sensitive actions.
For an architect, this turns into three early decisions. Every agent gets its own identity and a named owner. Every workflow gets an explicit mode: the agent acts as itself or on behalf of the signed-in user, which determines whose permissions apply. And the access boundary is written down before anyone tunes a prompt. Ownership deserves the most attention, because JumpCloud found that only 17% of organizations have a designated security leader accountable for AI agent actions.
Where should routing live: in agent code or in a gateway?
An agent that calls tools directly has to carry its own allow-list, credential handling, and retry logic. With ten agents, that means ten copies of the same logic, each updated on its own schedule by a different team. A gateway moves those decisions into one enforcement point that security and platform teams can review and change once.
On Google Cloud, Agent Gateway plays that role: all agent traffic can be routed through it, and policies there prevent agents from reaching unauthorized third-party endpoints. Identity-Aware Proxy for Agents bases access decisions on the agent’s identity plus context from the Model Context Protocol (MCP), while Context-Aware Access checks signals such as device health, IP address, and location. Model Armor runs inline at the gateway to catch prompt injection, tool poisoning, and sensitive data leakage.
The other half of routing is the path from agents to models and enterprise APIs. Apigee can act as an AI gateway in front of large language models, handling routing across models in different clouds, token limits, and semantic caching, so these controls are not rebuilt for every new LLM project. Model Armor’s inline protection already covers Apigee as well.
A gateway only governs the calls that pass through it. If an agent can reach a tool over a direct connection, the gateway’s policies never see that call. That is why VPC Service Controls now accept agent identities as principals in ingress and egress rules (in preview): direct egress can be blocked at the network perimeter, which leaves the gateway as the only route out.
What does observability need to capture for an agent?
A request log shows that an endpoint was called. After an agent incident, the questions go further: what goal the agent was pursuing, which tools it chose and in what order, what data came back, and why it took the next step. Google’s Agent Observability traces agent reasoning, tool use, and execution performance, and Agent Evaluation runs online monitors that flag performance degradation and behavioral drift in production. Agent Identity adds non-repudiable auditing of agent actions, and Agent Registry gives administrators a single inventory of agents, servers, and connections to keep agent sprawl in view.
“With tools like the Agent Development Kit, building an agent is now real programming, where the logic lives in code. The governance work starts once that code exists. The Agent Gateway and the Registry are what turn agents into manageable assets under centralized control, and evaluation and observability give teams a way to measure performance and see what their agents actually do in production,” says Andriana Zadorozhna, GenAI Engineer, Data & AI Solutions Architect at Cloudfresh.
Observability also decides whether a kill switch works in practice. To revoke an agent quickly, a team needs to know which agents exist, what each one can reach, and what it is doing right now. A registry answers the first question, identity-based policies the second, and live traces the third.
What does a controlled rollout look like in practice?
A company-wide generative AI rollout at a provider of digital business services with 1.5 million client companies followed this order. Before the assistant went live for analytics, marketing, product, and engineering teams, the rollout defined use cases, trained employees on models, context, and limitations, set up token and cost management, and configured access, roles, and admin settings. In the first month, 60% of employees used the assistant weekly, and time spent on document tasks dropped by 62%, from about two hours to 45 minutes.
A second example comes from a social discovery and relationship wellness company with more than 80 million users. Its first AI scenarios ran on open models hosted on rented GPUs, which lacked production-grade stability. After the team moved to Gemini on Gemini Enterprise Agent Platform, with specific models chosen per task and the architecture tuned for request cost and production load, automated review of profile descriptions went from 17% coverage to 100%. About 80% of profiles are now approved automatically in under five seconds, and fraud and safety incidents get a response in under a minute.
In both cases, the work around the model was part of the project scope alongside the use cases: access, roles, and cost controls in the first, a managed production platform in the second.
What should be decided before the first line of agent code?
The checklist below turns the three layers into decisions a team can make during design review:
- Registry entry and owner. Every agent gets a record in a registry and a named person accountable for its actions.
- Identity mode. Each workflow states whether the agent acts as itself or on behalf of a user, and the agent gets a dedicated identity in either case.
- Access boundary. Start from least privilege, then add hard limits, such as deny policies and principal access boundaries, for resources the agent must never touch.
- Gateway path. Route every tool and agent call through a gateway and block direct egress at the network perimeter.
- Human approval rules. Define which actions need sign-off before launch. JumpCloud’s data shows why this matters: human-in-the-loop approvals fall from 48% in testing to 29% in business-critical deployments.
- Traces and evaluation. Turn on tracing and online evaluation before go-live, so the first production incident already has a record.
- Revocation test. Confirm that a single action cuts the agent’s access across every system it touches.
Take the agent closest to production in your organization and run it through these seven items in your next design review. Any item without a clear answer goes on the backlog ahead of new features, because every capability added before that point widens access that no one yet controls.